From Elastic to OpenSearch: A Practical Migration Playbook for PeopleSoft Search
A practical migration playbook for PeopleSoft Search
“Why did the search engine take a vacation? It needed to index some time off.”
Migrating from Elasticsearch to OpenSearch is less about changing a product name and more about protecting a core business capability: fast, reliable search. For PeopleSoft administrators, the move affects the search engine, the PeopleSoft Search Framework configuration, index deployment, crawl operations, monitoring, and the operational runbook that keeps search from becoming an unexpected help-desk celebrity.
This article outlines a practical approach to planning, executing, and validating a move from Elasticsearch to OpenSearch in a PeopleSoft environment. It focuses on the technical decisions that matter most: compatibility, capacity, migration method, index handling, validation, and post-migration operations.
A quick reality check: search migrations rarely fail because someone forgot how to click Save. They fail because compatibility, data, capacity, or validation were treated as footnotes. Consider this article an attempt to move those footnotes into the main story.
Why move to OpenSearch?
OpenSearch is an open-source search and analytics platform built on Apache Lucene. In PeopleSoft environments, it serves as the search-engine platform used by the PeopleSoft Search Framework to store indexes and return search results.
The move away from Elasticsearch is driven primarily by platform support and product direction. Current PeopleSoft search capabilities continue to be enhanced around OpenSearch, so the migration should be approached as a lifecycle and supportability initiative—not simply as a like-for-like infrastructure replacement.
At a high level, the application experience remains familiar:
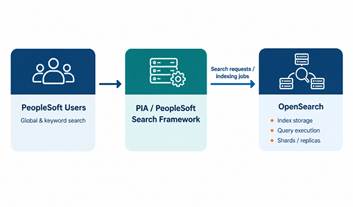
The change is under the hood, but its impact is visible wherever users expect a quick, relevant result. In other words, OpenSearch may be infrastructure, but it is infrastructure with a front-row seat in the user experience.
Start with discovery, not installation
Before selecting a migration path, capture the current Elasticsearch and PeopleSoft Search Framework state. A migration plan should document the existing search topology, software versions, index inventory, capacity profile, and integration configuration.
Build a migration inventory
At minimum, capture the following:
|
Area
|
What to document
|
Why it matters
|
|
PeopleTools level
|
Exact PeopleTools release and patch level
|
Determines the supported OpenSearch DPK, Java level, and delivered fixes
|
|
Current search engine
|
Elasticsearch version, installation location, HTTP port, cluster name, node count
|
Establishes the source environment and migration constraints
|
|
Search instances
|
Instance names, URLs, authentication configuration, active/default instance
|
Prevents the new instance from being configured with incorrect endpoints or credentials
|
|
Indexes
|
Search definitions, index sizes, document counts, last successful crawl
|
Defines migration effort, storage needs, and validation scope
|
|
Batch operations
|
Crawl schedules, run controls, Process Scheduler dependencies
|
Ensures indexing resumes after cutover
|
|
Infrastructure
|
CPU, RAM, disk, mount points, firewall rules, certificates, DNS
|
Avoids deploying a technically functional but operationally fragile service
|
|
Monitoring
|
Service checks, log locations, dashboards, alert thresholds
|
Lets operations detect issues before users do
|
Confirm compatibility first
Do not select a deployment package based solely on the newest file available. Match the OpenSearch DPK, supported Java runtime, PeopleTools release, and applicable patches to your PeopleSoft environment. Verify the applicable support documentation and patch requirements before implementation.
A useful rule: the PeopleTools version is the starting point for compatibility decisions, not the operating system. The operating system, Java version, and DPK must all align with that starting point.
Size for the real workload
Capacity planning should account for more than today’s data directory. Include:
· Current index size and expected growth.
· Temporary space needed for a data-copy migration.
· Replicas and shard overhead, if applicable.
· Log retention and diagnostic output.
· JVM heap requirements and operating-system memory.
· Re-indexing activity, which can increase I/O and CPU demand.
A practical baseline for a dedicated deployment is at least 4 CPU cores, 32 GB RAM, and 100 GB of available disk, with higher memory and storage targets for larger index portfolios. Keep the OpenSearch host separate from PeopleSoft application servers where possible; it makes resource behavior, maintenance, and troubleshooting much easier to manage.
Heap-size reminder: more heap is not automatically better. OpenSearch is Java-based, but the operating system also needs memory for file-system cache. Treat JVM tuning as a balancing act, not an all-you-can-eat buffet.
Choose the right migration path
There are three common approaches. The best path depends on downtime tolerance, infrastructure design, index volume, and confidence in data-folder compatibility.
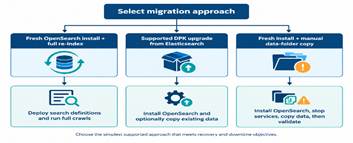
Option 1: Fresh installation and full re-index
This is typically the cleanest and lowest-risk choice from a data-integrity perspective.
1. Install OpenSearch on a new or dedicated host using the supported deployment package.
2. Configure a new OpenSearch search instance in PeopleSoft.
3. Apply required PeopleSoft fixes and delivered search definitions.
4. Deploy the required search objects.
5. Run full index builds/crawls.
6. Validate results, performance, and operational jobs before cutover.
Advantages
· Avoids relying on low-level index-data compatibility.
· Produces a clean, reproducible environment.
· Simplifies rollback because Elasticsearch remains unchanged until cutover.
· Best fit for large version gaps, uncertain legacy history, or complex clusters.
Trade-offs
· Can require substantial crawl time and application/database resources.
· Requires enough time and capacity to build indexes from source data.
For many organizations, this is the preferred method. Re-indexing may take longer, but it replaces uncertainty with a measurable, testable process.
Option 2: Use the supported DPK upgrade path
Where supported for the source and target versions, the deployment package can perform an Elasticsearch-to-OpenSearch upgrade and offer to copy existing data during the process.
A representative Linux command pattern is:
./psft-dpk-setup.sh --os_upgrade --install_base_dir <OSK_BASE_DIR>
During the upgrade, the process typically requests source Elasticsearch location, OpenSearch credentials, cluster/port details, data and log locations, and JVM heap configuration. It may then offer to copy the existing search data.
Advantages
· Streamlines installation and migration tasks.
· Can reduce manual file handling.
· Useful when the environment fits the supported upgrade pattern.
Trade-offs
· Requires close attention to supported source versions and DPK instructions.
· A successful installation does not replace functional validation.
· Data-copy duration and disk requirements can be significant.
Option 3: Fresh installation plus manual data-folder copy
This method installs OpenSearch separately and then copies the existing Elasticsearch data directory into the target location. It can be attractive when a fast cutover is important, but it carries more operational risk.
Use caution. Data-folder copying should be tested in a nonproduction environment that closely resembles production. It is more sensitive to version compatibility, data volume, permissions, service stop/start order, and cluster topology.
It is generally less suitable as a first-choice method for multi-node or complex clustered environments. If there is any doubt, choose the fresh-install/full-reindex route.
Technical implementation workflow
The following workflow combines the strongest practices across migration paths while preserving a clear rollback option.
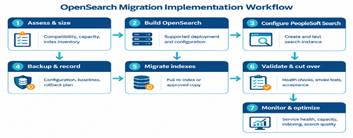
1. Prepare the target host
· Provision a supported 64-bit operating-system host, physical or virtual.
· Use dedicated data and log paths with appropriate ownership, permissions, and backup coverage.
· Confirm DNS resolution, network connectivity, firewall rules, and port availability.
· Reserve capacity for the OpenSearch data directory, logs, temporary copy operations, and future growth.
· Establish service-management, restart, and monitoring procedures before production cutover.
2. Install and configure OpenSearch
For a fresh installation, a representative command pattern is:
./psft-dpk-setup.sh --install --install_base_dir <BASE_DIR>
Typical installation inputs include:
· OpenSearch administrator and proxy credentials.
· HTTP port, commonly 9200 unless your topology requires a different port.
· Discovery hosts for the intended topology.
· Data and log locations.
· JVM heap size.
Treat all credentials as secrets. Store them in the organization’s approved credential-management solution rather than in shell histories, scripts, tickets, screenshots, or personal notebooks. Search may be fast, but secrets should never be searchable.
3. Create the PeopleSoft search instance
In PeopleSoft, navigate to:
PeopleTools > Search Admin Activity Guide > Search Instance
Create a new OpenSearch-based instance and supply the target host, port, protocol, and required credentials. Avoid immediately overwriting a working Elasticsearch instance. Keeping the source instance intact during testing supports controlled validation and a practical rollback path.
4. Deploy search definitions
Navigate to:
PeopleTools > Search Admin Activity Guide > Deploy/Delete Object
Select the new OpenSearch instance, choose the required search definitions, and deploy them. Verify that deployment completes successfully and that expected objects appear in the target environment.
For upgrade scenarios that use deployment-data copy, inspect the resulting definitions and run controls carefully. Naming conventions may distinguish OpenSearch-deployed objects from Elasticsearch-deployed objects, and copied deployment data should be verified rather than assumed correct.
5. Populate the indexes
For a full rebuild, use:
PeopleTools > Search Admin Activity Guide > Schedule Search Index
Select the OpenSearch instance, choose the search definition, select Full Index, and run the process. Schedule crawls in a sequence that respects business priority and system capacity. Large or high-usage indexes should be tested early so that timing and performance concerns are known before cutover.
6. Validate before cutover
Validation should prove both technical health and user-visible correctness.
|
Validation area
|
What good looks like
|
|
Service health
|
OpenSearch starts reliably, remains available, and reports a healthy status
|
|
Connectivity
|
PeopleSoft can authenticate and communicate with the intended OpenSearch endpoint
|
|
Deployment
|
Required search definitions deploy without errors
|
|
Index content
|
Document counts and expected records are present after crawl or data migration
|
|
Search behavior
|
Representative keyword, faceted, and global-search queries return expected results
|
|
Performance
|
Search response time is acceptable under expected load; indexing completes within the operational window
|
|
Batch operations
|
Scheduled indexing and incremental updates run successfully
|
|
Security
|
Credentials, transport configuration, host access, and certificates meet local standards
|
|
Observability
|
Logs, alerts, service checks, and dashboard metrics are active and actionable
|
Use a test script with representative searches rather than relying on a few convenient queries. Include searches for common terms, partial terms, names with punctuation, synonyms or special characters where relevant, security-filtered results, and records recently added or changed.
Cutover and rollback strategy
A successful technical install is not the same as a successful cutover. Plan the switch as an operational event with explicit entry and exit criteria.
Suggested cutover sequence
1. Complete a final health check of the new OpenSearch service.
2. Confirm all required definitions are deployed and indexes are current.
3. Pause or redirect scheduled crawl jobs as needed.
4. Change the active PeopleSoft search instance to OpenSearch.
5. Execute predefined smoke tests from both administrator and end-user perspectives.
6. Monitor logs, response time, CPU, memory, disk utilization, and error rates during the agreed stabilization period.
7. Keep the Elasticsearch instance and its configuration available until acceptance criteria are met.
Rollback principle
A rollback plan should be simple enough to execute under pressure. In most cases, the cleanest rollback is to restore the prior PeopleSoft search-instance selection and re-enable the Elasticsearch-side schedules, provided the source environment remains intact and current enough for the rollback window.
Document exactly who can authorize rollback, what configuration change performs it, and how indexing schedules will be handled. If the rollback plan requires everyone to “figure it out live,” it is not a plan; it is an improv show with production data.
Operational lessons and pitfalls
Prefer full indexing when confidence matters
A full index build is the most reliable way to establish a known-good OpenSearch dataset. It may take longer, but it avoids inheriting unknown data-state issues from older environments.
Treat copied data as a migration accelerator, not proof
Copying a data folder can work well in compatible, tested scenarios, but it does not eliminate the need to verify index completeness, search behavior, and PeopleSoft deployment metadata. Be especially cautious with large indexes and clustered deployments.
Do not overlook encryption and credential differences
Elasticsearch and OpenSearch may handle encryption and stored credentials differently. Revalidate service accounts, passwords, certificates, keystores, and any connection settings after the migration. A search engine can be perfectly healthy while the application cannot authenticate to it.
Monitor the right signals
At a minimum, monitor:
· OpenSearch process and service availability.
· Cluster or node health, where applicable.
· JVM heap use and garbage-collection behavior.
· CPU, memory, disk capacity, disk latency, and inode usage.
· Indexing duration and job failures.
· HTTP/transport errors, authentication failures, and connection timeouts.
· Search response latency and error rates.
· Data and log-directory growth.
Keep a version-and-patch record
Record the PeopleTools release, OpenSearch DPK version, Java version, applied patch identifiers, configuration files, ports, service names, data paths, and log paths. This becomes invaluable during patching, incident response, audits, and the inevitable question: “What changed last weekend?”
A practical checklist
Before migration
· Confirm PeopleTools, OpenSearch DPK, Java, and patch compatibility.
· Inventory search instances, definitions, indexes, schedules, and run controls.
· Size CPU, memory, data storage, log storage, and temporary copy space.
· Select the migration method and document the rationale.
· Back up configuration and capture baseline health and performance.
· Prepare a test plan, cutover plan, communications plan, and rollback plan.
During migration
· Install OpenSearch using the supported deployment procedure.
· Configure a separate PeopleSoft OpenSearch search instance.
· Deploy search definitions.
· Perform approved data migration or full crawling.
· Capture installation output and configuration values in the implementation record.
Before production cutover
· Verify service health, connectivity, authentication, and logs.
· Compare expected index content and test representative searches.
· Validate scheduled indexing and operational monitoring.
· Obtain acceptance from technical and business stakeholders.
After cutover
· Closely monitor performance, indexing, errors, capacity, and user-reported search quality.
· Keep the prior environment available until the rollback window expires.
· Update runbooks, diagrams, monitoring documentation, and disaster-recovery procedures.
· Schedule a post-implementation review to capture lessons for the next environment.
Final thoughts
The move from Elasticsearch to OpenSearch is an opportunity to modernize more than the search engine. It is a chance to improve capacity planning, monitoring, documentation, credential handling, and the repeatability of search operations across environments.
The safest migration is usually the one that is easiest to explain: build a supported OpenSearch environment, configure it separately, deploy and populate indexes, validate thoroughly, cut over deliberately, and retain a clear path back until confidence is earned.
OpenSearch can make enterprise search feel effortless for users. The administration behind it will not always be effortless—but with the right planning, it can be predictable. And in production operations, predictable is often the closest thing we get to magic.